
Silk DataPod: The High-Performance Data Layer for Your Cloud
A Silk DataPod turns standard cloud compute and storage into one high-performance data platform. Your databases connect to it just like native cloud block storage, with no code changes and no rearchitecting.
Native Cloud Disks Tie Performance to Capacity
With native cloud block storage, getting more performance usually means buying a bigger disk, a premium tier or a larger VM, whether you need the capacity or not. A Silk DataPod separates the two, so you pay for the performance and capacity you actually use.
Native Cloud Storage
- Performance tied to disk size and tier
- Overprovision capacity to get the IOPS you need
- Full copies consume capacity, time and budget
Silk DataPod
- Performance and capacity scale independently
- Up to 100× faster database performance
- Up to 69% lower cloud costs
- Zero-footprint snapshots and clones
- No application or database changes
What's Inside a Silk DataPod
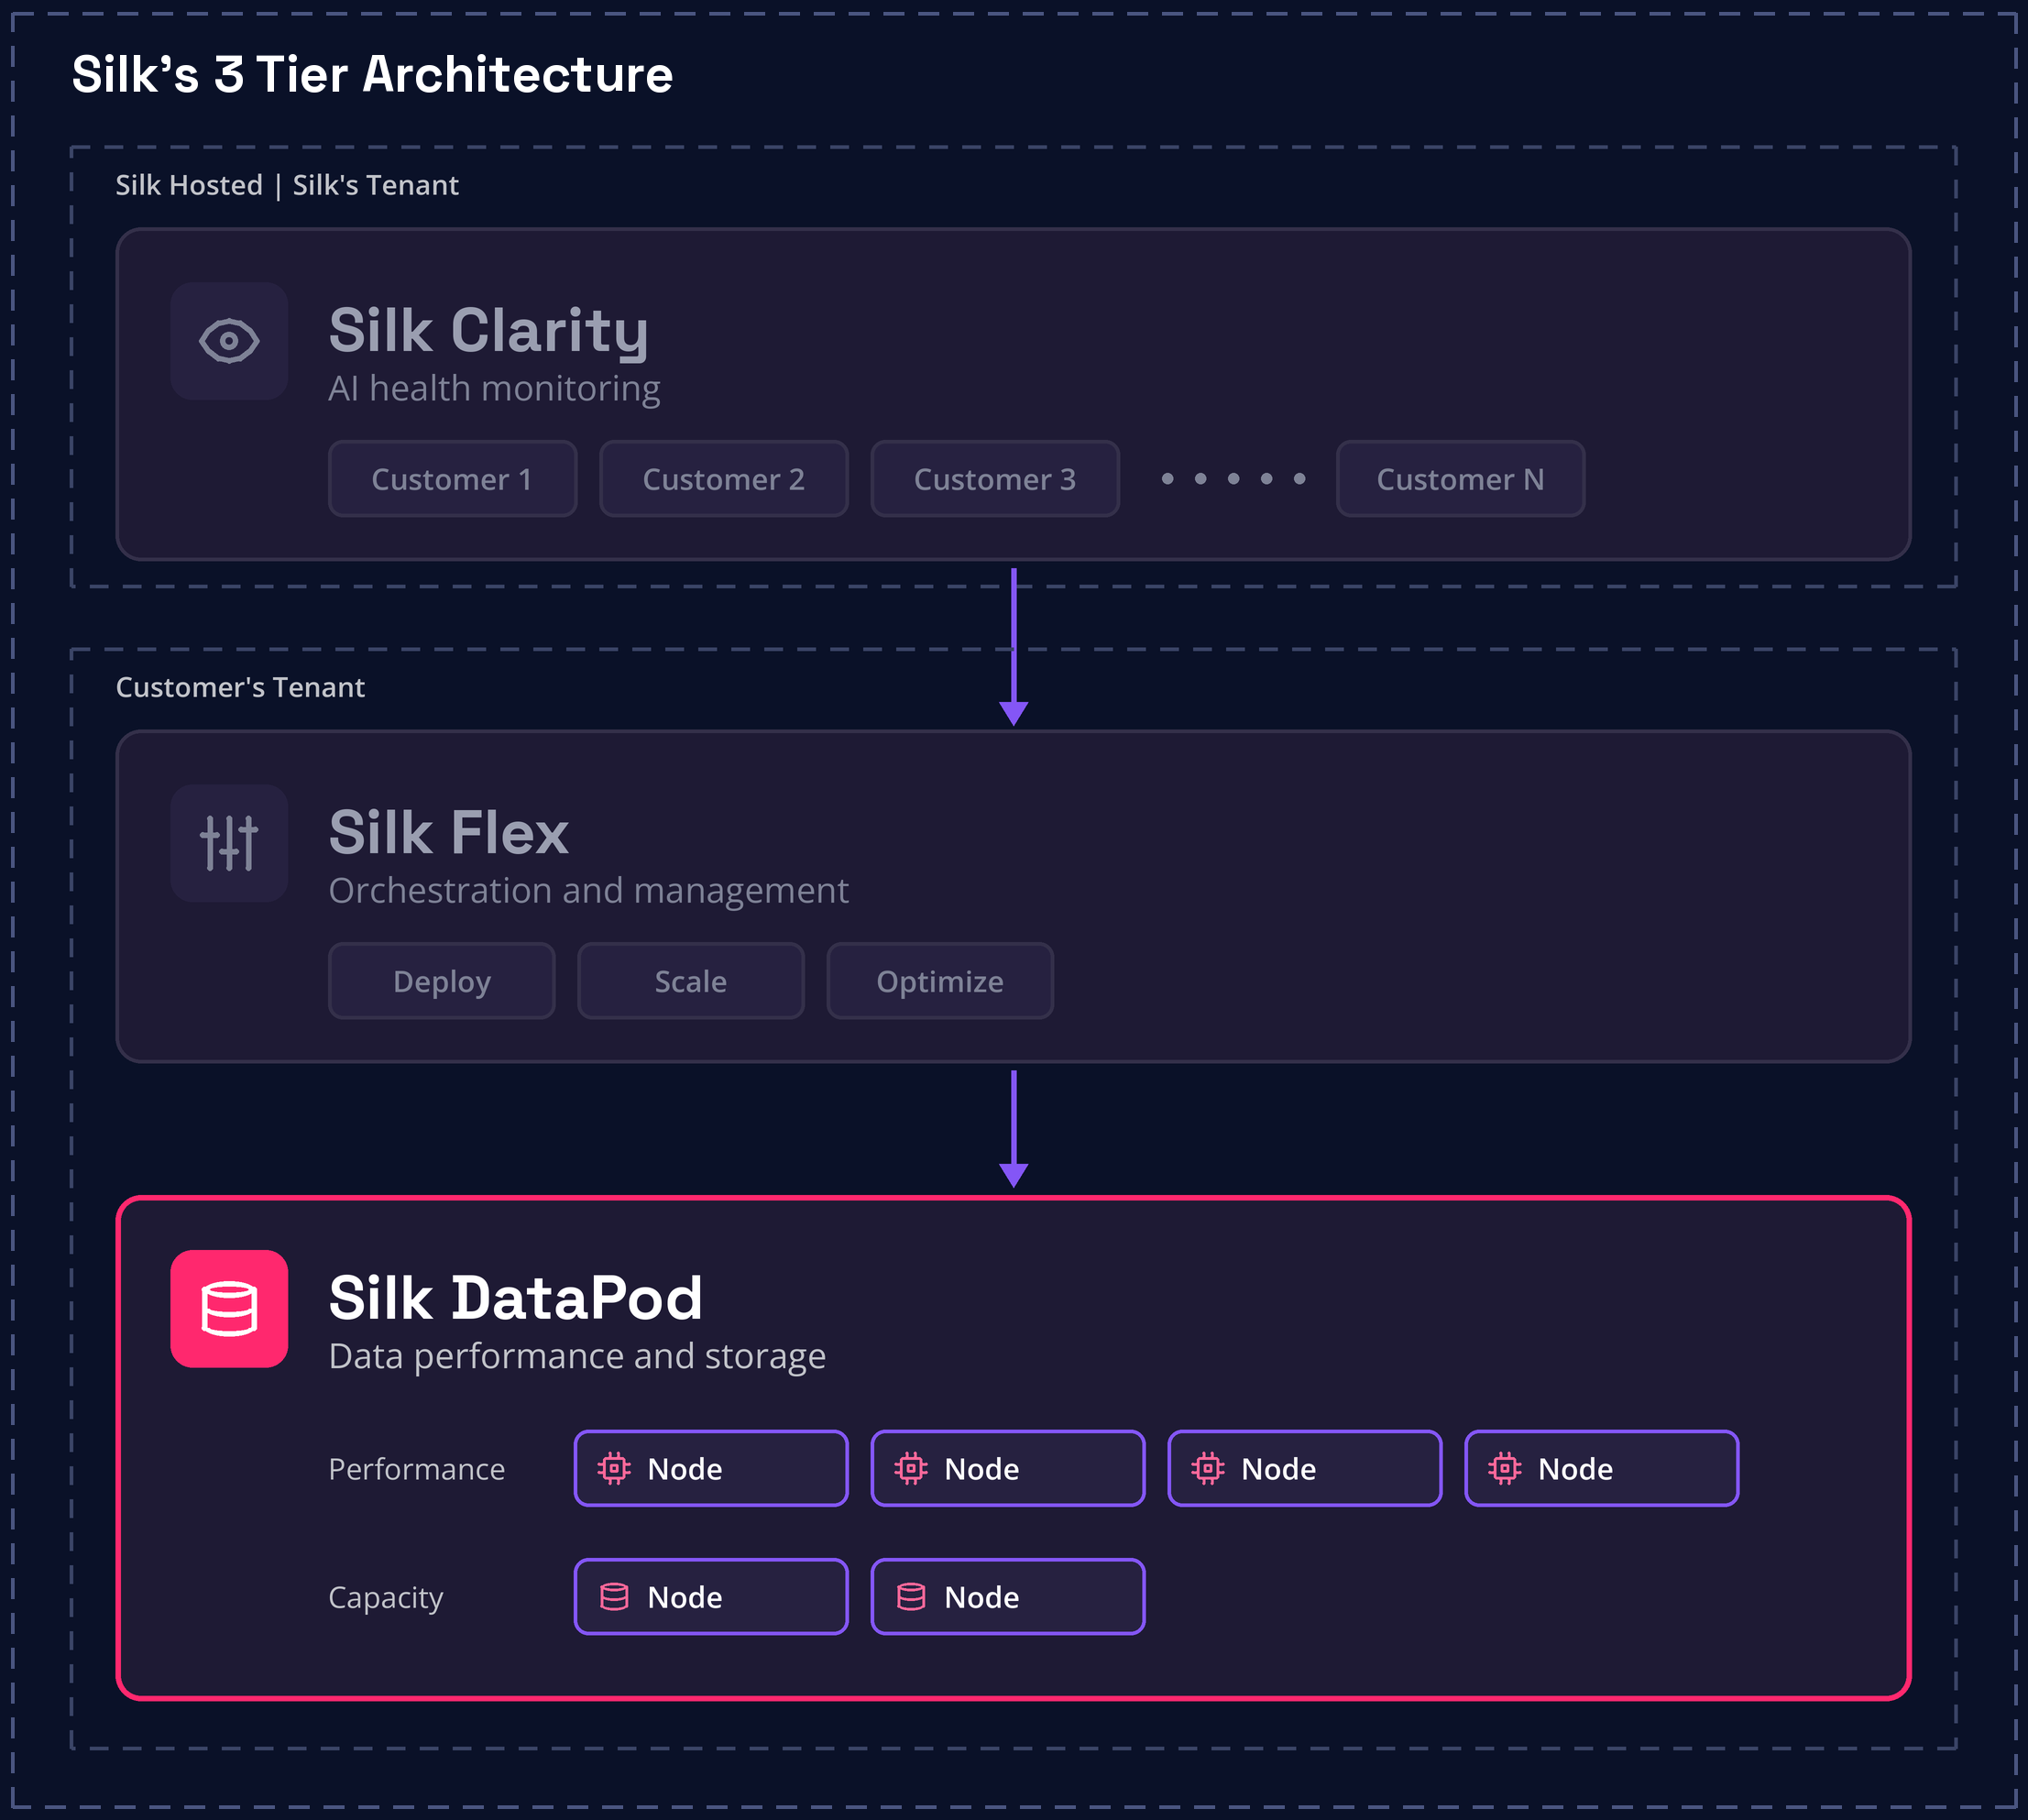
Every Silk DataPod combines a performance layer, a capacity layer and built-in data services.
Performance layer
Silk compute nodes serve I/O in parallel for consistent low latency and high throughput. Add nodes when demand rises and remove them when it drops.
Capacity layer
Data lives on cloud media managed by Silk. Capacity scales on its own, so you never overbuy one to get the other.
Inline data reduction
Compression, deduplication and thin provisioning shrink your data footprint, so you store and pay for less.
Zero-footprint snapshots and clones
Create writable copies of production instantly, with no extra capacity until data changes.
Silk Echo
Give dev/test, analytics and AI teams production-grade database copies that run alongside production without slowing it down.
Replication and recovery
Built-in replication and snapshots let you restore production data in minutes after an outage or ransomware attack.
How a Silk DataPod Serves Your Databases
Your applications see standard block volumes. The Silk DataPod does the heavy lifting underneath.
Your databases
SQL Server, Oracle, PostgreSQL
Silk volumes
Connect like native block storage
Silk DataPod compute nodes
Serve I/O in parallel
- Data reduction
- Snapshots
- Clones
- Replication
Cloud capacity
Media managed by Silk
Add compute nodes to raise performance on demand, and remove them when demand drops.
Why Teams Choose Silk DataPods
Performance you can scale, costs you can predict, and no changes to your applications.
Scale performance on demand
Raise throughput for peak periods or heavy batch windows, then scale back down, without migrating data or resizing disks.
Pay for what you use
Each Silk DataPod is priced on the capacity and throughput you provision, so you stop paying for idle premium storage and oversized VMs.
Runs in your cloud
Silk DataPods are deployed in your own AWS, Microsoft Azure, Google Cloud or AI cloud environment, so your data stays where it lives today.
Works with your databases
SQL Server, Oracle, PostgreSQL, analytics and AI workloads use Silk DataPod volumes exactly as they use native cloud disks.
Proven in production
In a commissioned Forrester Total Economic Impact study, the composite organization cut cloud storage costs on its Silk workloads by 50%.
Explore the Silk Platform
See a Silk DataPod in Action
Bring one workload and see how a Silk DataPod changes its performance and its cloud bill.