AI Clouds / Tokenomics

Lower Cost per Token Starts With the Data Layer

Every token you serve carries the cost of the GPU, the power and the storage behind it. Silk works on both the cost and the output: faster data keeps GPUs productive, and dynamic scaling and instant copies stop you paying for capacity you don't use.
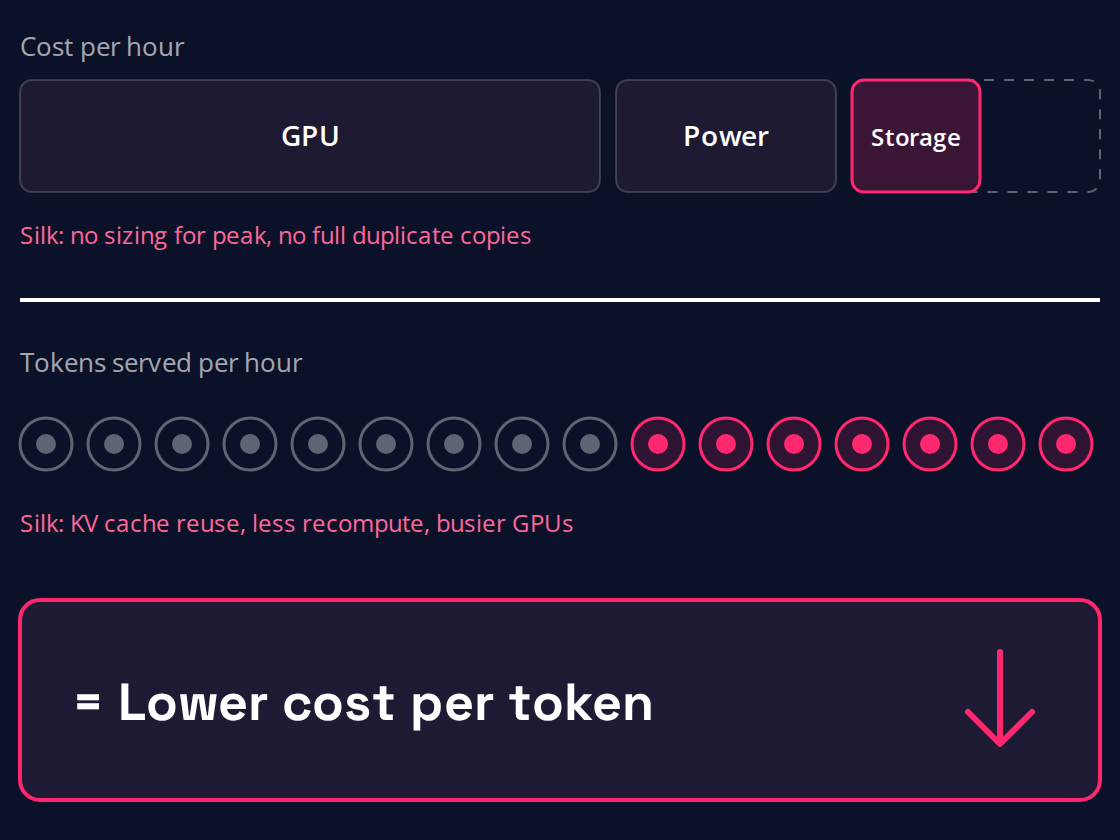
Diagram: cost per token is cost per hour divided by tokens served per hour. Silk shrinks the storage cost and increases the tokens served, giving a lower cost per token

The Real Cost Is a GPU Waiting

A GPU that's stalled on data, or recomputing context it already processed, costs the same per hour and draws the same power. When the data layer cannot keep up, utilization falls and the cost of every token rises. Storage sized for peak and duplicated for every copy adds a second layer of waste on top.

The Tokenomics Equation

Silk works on both parts of it.

Cost per token = GPU + power + storage cost per hour ÷ tokens served per hour
Silk shrinks the cost side: no overprovisioning, no duplicate copiesSilk grows the tokens side: less recompute, more sessions per GPU

GPU utilization

Keep GPUs serving instead of waiting. A persistent KV cache tier cuts repeated prefill, and high-throughput, low-latency block access keeps data arriving as fast as the GPU can use it.

Cost per token

Up to 5× better cost per token with a Silk KV cache tier.² Serve more tokens from the GPUs you already own, and stop paying for storage you don't need. Scale performance and capacity independently, up and down, as demand moves.

Energy

Every prefill you do not recompute is GPU power you do not spend. Zero-footprint copies, compression, deduplication and right-sized storage mean less hardware drawing power in the rack.

Performance and Efficiency on One Platform

You don't have to trade one for the other.

The performance lever

Get more output from the most expensive asset in your data center.

  • Persistent KV cache reuse instead of recomputed prefill
  • More concurrent sessions and longer contexts per GPU
  • 35.6 GB/s and 1.2M+ IOPS measured from a single client¹

The efficiency lever

Spend only on the data infrastructure your tenants actually use.

  • Dynamic scaling: add or remove performance without moving data
  • Instant, zero-footprint copies instead of full duplicates
  • No sizing for peak, no idle capacity bought just in case
  • Inline compression and deduplication cut the capacity you pay for

Up to 5× better cost per token with a Silk KV cache tier²

Try the Tokenomics Calculator

See What Silk Does to Your Cost per Token

Tell us about your GPU fleet and workloads, and we'll model the impact with you, with every assumption shown.

  1. 1. Single client results. 35.6 GB/s: one 200GbE NIC, mixed workload of roughly 65% reads / 35% writes, duplex figure. 1.2M+ IOPS: measured in public cloud; full DataPod IOPS is tested across multiple clients.
  2. 2. Silk analysis comparing inference with a KV cache tier against no KV cache.